Post-call analysis
Post-call analysis
Post-call analysis turns every finished call into structured data — a summary, sentiment, an outcome (disposition), action items, objections, your own custom fields, a QA rubric score, and an LLM-judge scorecard — without anyone listening to a recording. It runs automatically in the background after a call ends and never blocks the call itself.
It is configured per agent (not per organization): each agent has its own enable toggle, custom fields, and QA rubric, saved on the agent as metadata.postCallAnalysis. The analysis runs through Telenow's managed LLM layer, and the token cost is metered and billed to your organization like any other model usage (see Usage & billing).
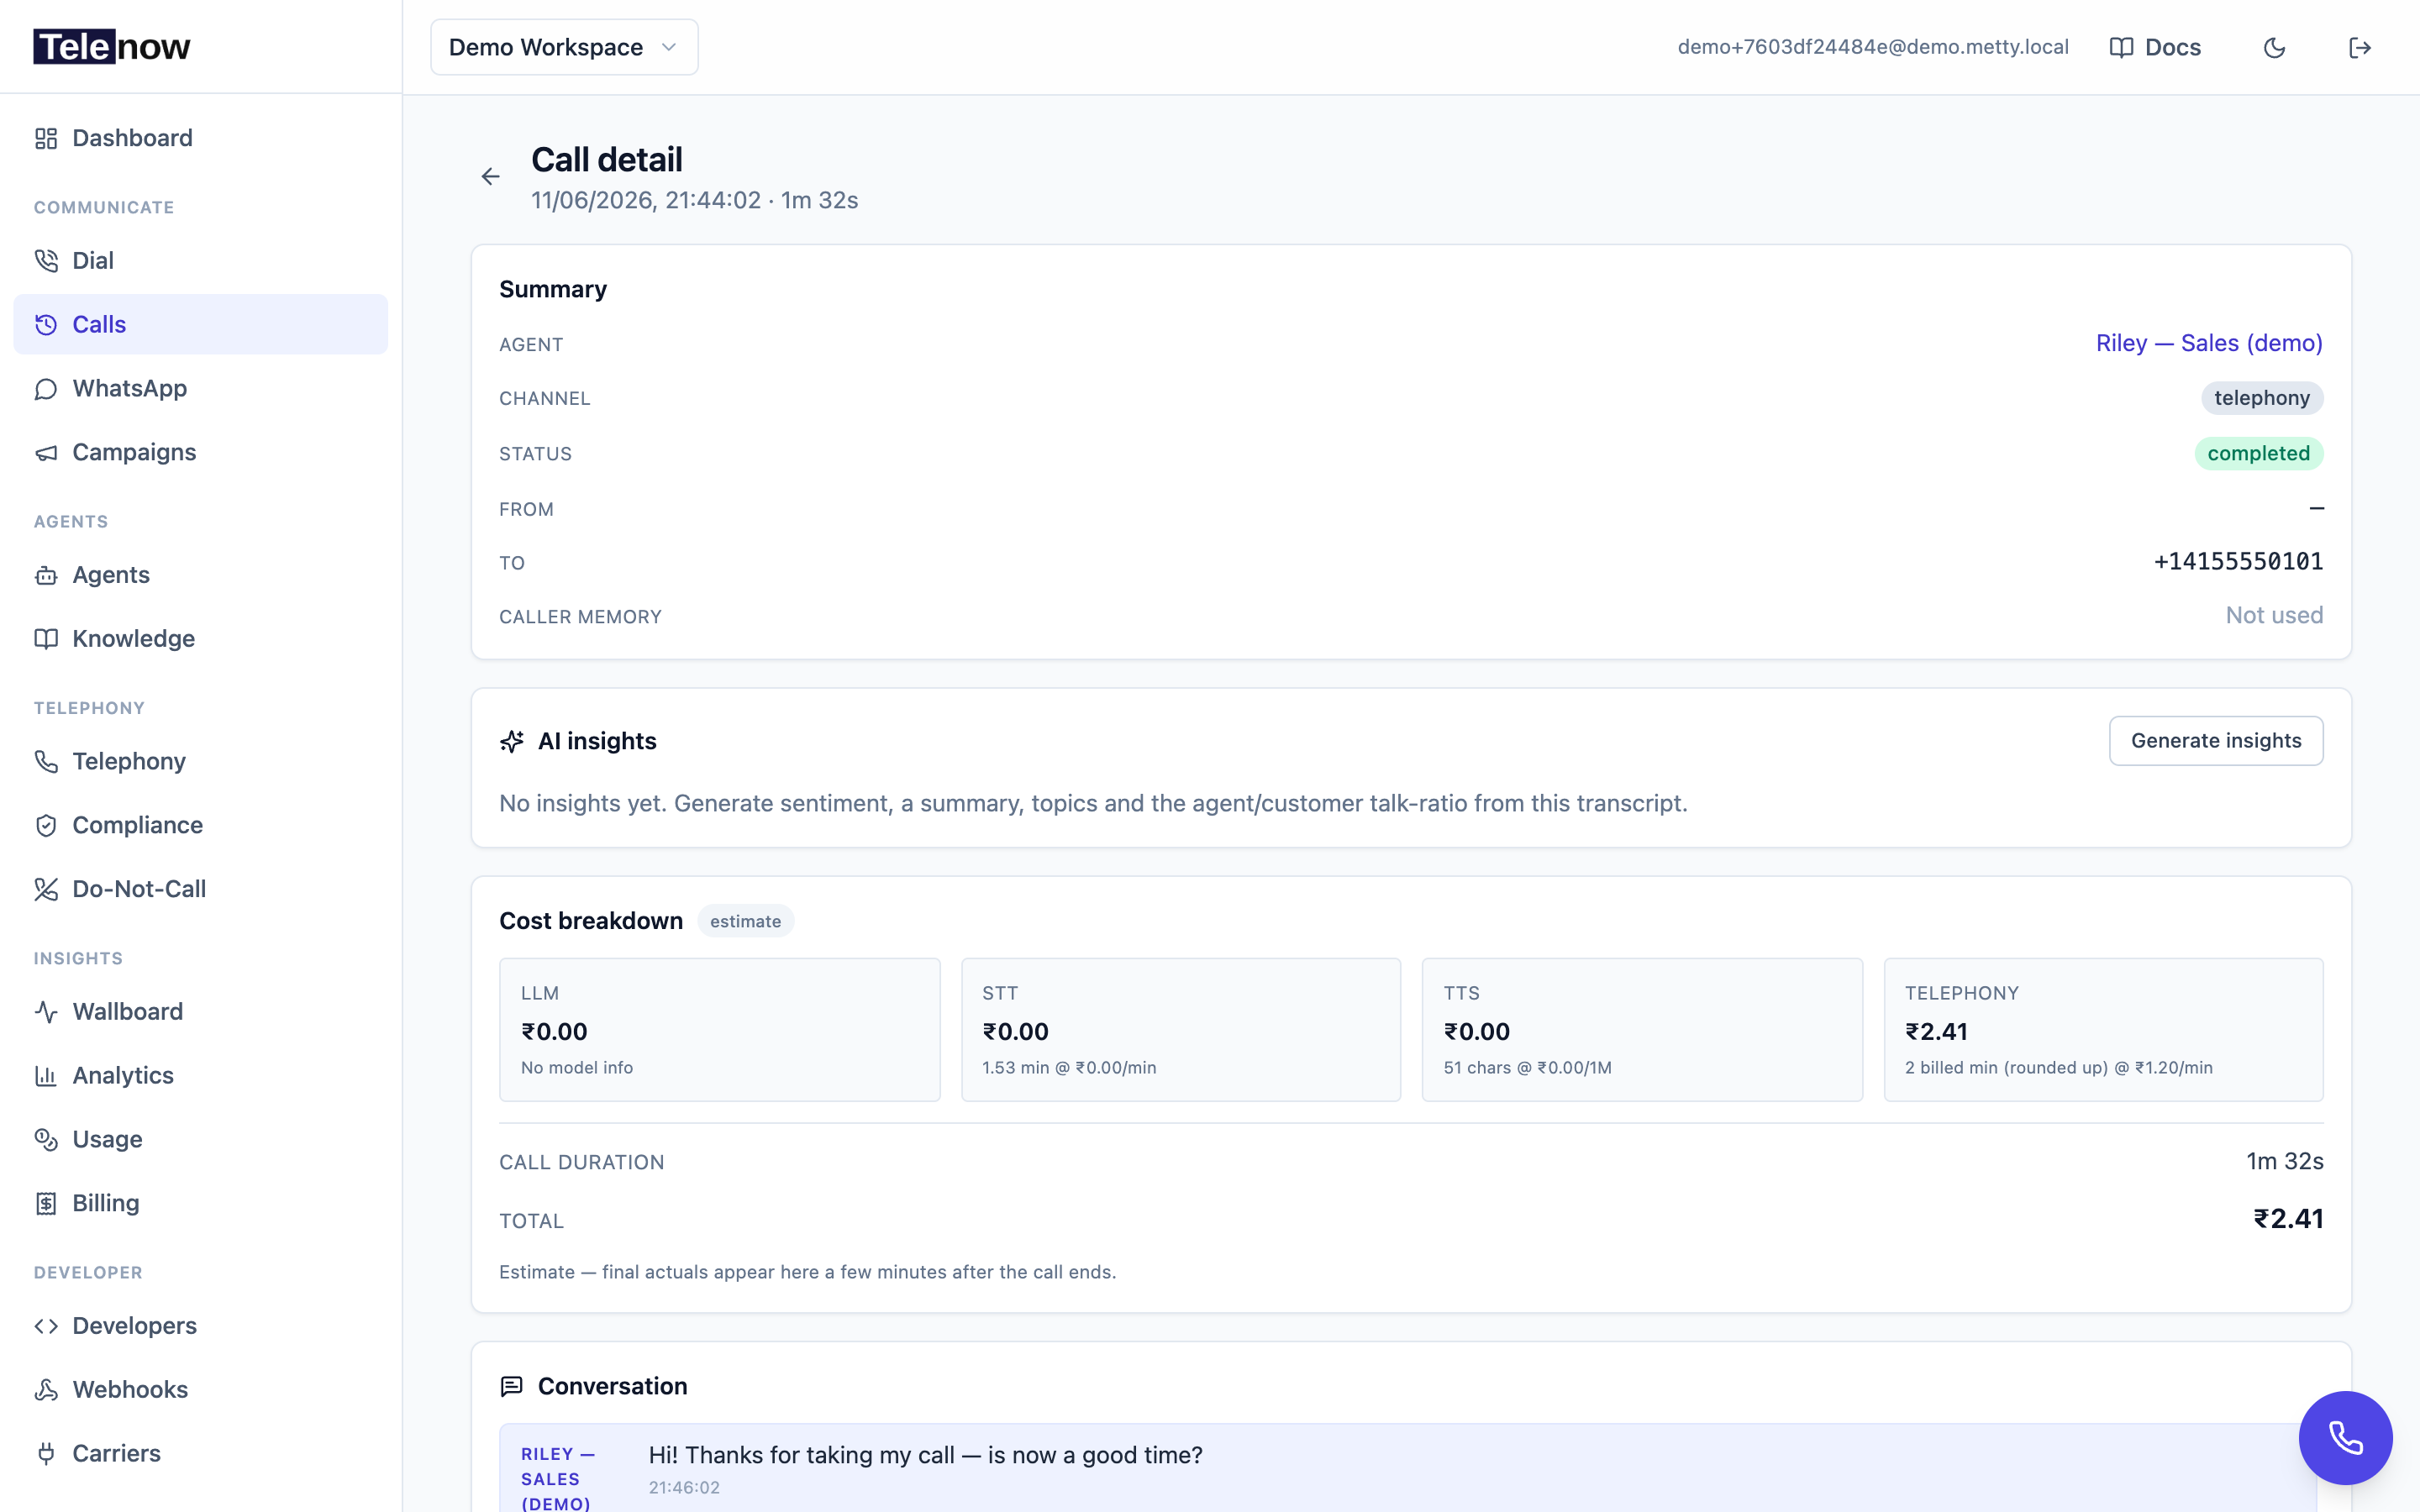
Analysis results appear on the call's detail page — alongside AI insights, the transcript, and the cost breakdown.
Enable it
In the agent builder, open the Analysis step and turn on Enable post-call analysis for this agent. Doing so adds an Analysis tab to the agent and starts analyzing every call it finishes from then on. Two things are configurable below the toggle:
Which calls get analyzed
Not every finished call is worth an AI pass. A voicemail beep the agent talked over, a hangup one word into the greeting, an IVR that answered and punted — each of those bills a full analysis and returns nothing you would act on. Two thresholds sit directly under the toggle:
| Setting | Applies to | Default |
|---|---|---|
| Skip calls shorter than | Voice calls — phone, browser calls, softphone | 20 seconds |
| Skip chats with fewer customer replies than | WhatsApp, Instagram, web chat | 2 customer replies |
Set either to 0 to analyze everything.
Text conversations are measured in replies rather than seconds on purpose. A chat's duration is the wall-clock gap between its first and last message, so it records how long the customer took to answer, not how much was said — a chat resolved in fifteen seconds would be thrown away while one left idle for ten minutes with two messages would be kept.
A skipped call produces no analysis at all — no row, no cost, and no entry in the disposition, objection or QA rollups on the agent's Analysis tab. That last part is the one to weigh before raising the threshold: if a typical "not interested" on your campaign runs 25 seconds and you set the minimum to 45, the rollup will report that you meet almost no objections. 20 seconds is the default because it clears voicemail and instant hangups while still keeping short real outcomes — a confirmation, or a refusal.
Both thresholds are per agent, saved as metadata.postCallAnalysis.minDurationSec and metadata.postCallAnalysis.minCustomerTurns, and are read from the config the call actually ran under — so changing one today never re-grades or retroactively skips calls that already happened.
Custom fields
Your own extraction targets — facts you want pulled out of every call. Click Add field and fill three columns:
| Column | Meaning |
|---|---|
| key | The JSON property the value is stored under (e.g. budget, order_id, competitor_mentioned). Required. |
| description | What the model should pull — plain-English instructions (e.g. "the caller's stated monthly budget"). |
| type | One of string, number, boolean, date. Unknown types are coerced to string. |
Up to 30 custom fields per agent. When a field can't be determined from the transcript the model sets it to null rather than guessing, and (where possible) records a verbatim supporting quote in the call's evidence. Extracted values land in the call's customData, keyed by your key. Entries with a blank key are dropped on save.
QA rubric (agent scorecard)
A list of yes/no criteria the model grades the agent against. Click Add criterion and give each:
- key — a short identifier, e.g.
verified_identity,read_disclosure. - criterion — the yes/no question, e.g. "Did the agent verify the caller's identity before sharing account info?"
Each criterion is scored met / not-met with a supporting verbatim quote, returned in the call's qa array as { key, met, evidence }. The rubric is also capped at 30 entries; keyless rows are dropped.
The config (fields + rubric) is preserved even if you toggle analysis off, so re-enabling later restores your setup.
What you get
Each analyzed call produces:
| Field | Description |
|---|---|
summary | A one-to-two-sentence recap of the call |
sentiment / sentimentScore | Overall caller sentiment (positive / neutral / negative) + a score from −1 to 1 |
disposition | A short snake_case outcome label (e.g. resolved, escalated, booked, not_interested, callback, no_answer) |
actionItems | Concrete follow-ups detected in the conversation |
objections | Concerns/objections the caller raised |
customData | Your custom fields, keyed by their key |
evidence | Verbatim transcript quotes backing key judgments and extracted fields (a hallucination guard) |
qa | Your QA rubric scored met/not-met with evidence |
score | An LLM-judge overall quality score, 0–100 |
coaching | Concrete ways the agent could improve (issue, suggestion, severity) |
hallucinations | Claims the agent made that contradict its instructions or aren't supported by the transcript |
cx | A customer-experience read (rating, friction, highlights) |
topics / keywords | Aggregatable tags (up to ~5 topics, ~8 keywords) describing the call |
talkRatio | Four counts: agentWords, customerWords, agentTurns, customerTurns |
The talk ratio is reported as those four raw counts (computed deterministically from the transcript, no LLM). The familiar agent-vs-customer percentage is derived from them on the client — so you can compute it however you like.
The LLM-judge passes (score, coaching, hallucinations, cx) are grounded strictly on the transcript and the agent's own system prompt — the judge is told not to invent external facts, which is what makes the hallucination flags meaningful.
When it runs
A background worker claims finished calls roughly every 30 seconds and only looks back a couple of hours, so analysis lands shortly after a call ends. It never blocks the call, survives restarts, and retries on failure. Turning analysis on affects calls going forward — it does not back-fill old calls. Analysis needs a non-empty transcript; calls with no speech are marked failed.
Where to see it
- Call detail — open any call in Calls; the analysis appears as a card once it's ready.
- Agent → Analysis tab — rollups across a date range: average score, sentiment trend, disposition breakdown, top objections, top topics/keywords, talk ratio, and how many calls had hallucination flags. See Analytics.
API & webhook
| Method | Path | Purpose |
|---|---|---|
GET | /api/orgs/{orgId}/analysis/result/{sessionId} | The stored analysis for one call (data is null until it has run) |
GET | /api/orgs/{orgId}/analysis/cost?from&to | Total platform-AI cost billed to the org over the window |
GET | /api/agents/{id}/analysis/rollup?from&to | Aggregated KPIs + trends for an agent |
GET | /api/agents/{id}/analysis/calls?from&to | Recent analyzed calls for an agent |
These are dashboard routes — they return { success, data } and use your normal session auth within an org. When analysis completes, Telenow also fires the call.analyzed webhook carrying the full analysis object (scoped to the call's agent) — the easiest way to push results into your CRM or warehouse without polling. The call.analyzed payload's talkRatio carries the same four counts described above.
Tips
- Write custom-field descriptions like instructions to a junior analyst — the clearer the description, the more reliable the extraction.
- Make QA criteria genuinely yes/no. "Was the call good?" grades poorly; "Did the agent state the cancellation policy?" grades well.
- Use
dispositionfor funnel reporting andcustomDatafor the specifics — both aggregate on the Analysis tab.
Troubleshooting
- No analysis card on a call — confirm the agent's Analysis toggle is on, give the worker up to a minute, and check the call actually has a transcript (a call with no caller speech can't be analyzed).
- A custom field is always
null— the model couldn't find it in the transcript (by design it won't guess). Tighten the description, or check the information was actually said on the call. - Old calls have no analysis — analysis only applies going forward; it doesn't back-fill calls from before you enabled it.
Related
- Caller memory — remember individual callers across calls (configured on the same Analysis step).
- Analytics — the agent Analysis-tab rollups in depth.
- Calls, recordings & insights — where analyzed calls surface.
- Webhook events — the
call.analyzedpayload.
Getting the results out
Everything analysis extracts — summary, sentiment, and your own custom fields — can be written straight into a Google Sheet or Airtable table as each call ends. See Call destinations.